Showing posts with label simulation. Show all posts

Sunday, July 31, 2016

Barber Queue

Time was when I needed a hair cut, I'd go at noon on a weekday, when the barber's is typically empty. One of the perks of being unemployed.

But these days I have to get my haircuts on Saturdays, before noon. Which is bad enough in itself - ideally I'd never see Saturday mornings at all. And to make matters worse, Saturday morning is also when the barbers is at its busiest.

Hence, I found myself sat in the waiter area of a barbershop for the best part of an hour. But this got me thinking about how queuing works at a barbers.


First In Who's Next?

At its core, the barber's queue is just a first-in first-out (FIFO) queue. But it has two interesting features:


1) The queue 'structure' is unordered

In general the queue 'structure' will be a waiting area with a bunch of seats. When someone new joins the queue, they're free to sit wherever. In fact, odds are, they'll pick a seat in a similar way to how men choose urinals - attempting to maximise personal space.

But the key point is, if someone were to just look at the queue, they wouldn't be able to tell who was next.


2) Each member of the queue knows whether or not they're next

Each member of the queue probably doesn't know who exactly is next, but they do know (with reasonable certainty) whether or not it's them.

The way this works is relatively simple - when you join the queue, you're aware of who was there when you arrived (and of anyone who arrives after you). So when all the people who were there ahead of you have gone, you know that you're next.


O(M G)

Okay, lets break out some Python (2.7)

Just for fun, let's say that the capacity of the queue is fixed - i.e. the waiting area has a fixed number of seats (though in practice, people are free to stand, as I was forced to).

class BarberQueue(object):

    def __init__(self, capacity):
        self._capacity = capacity
        self._queue = [None]*capacity
        self._length = 0

    def __len__(self):
        return self._length

    def __str__(self):
        return ', '.join(str(i) if i is not None else '_'
                         for i in self._queue)

    def push(self, obj):
        pass

    def pop(self):
        pass

So each member of the queue has some awareness of who is ahead of them. But they don't need to know specifically who's who, they just need to keep track of how many are remaining. And in fact, that remaining count is exactly equivalent to the member's position in the queue.

class Member(object):

    def __init__(self, obj, position=0):
        self.value = obj
        self._position = position

    def __str__(self):
        return "%s (%s)" % (self.value, self._position)

    def is_next(self):
        return self._position == 0

    def move_up(self):
        self._position -= 1

So, going back to the push and pop methods

def push(self, obj):

    if self._length == self._capacity:
        raise Exception("Queue is full! Please come back later.")

    for i, m in enumerate(self._queue):
        if m is None:
            self._queue[i] = Member(obj, self._length)
            self._length += 1
            return

Here, we're picking a 'seat' by iterate over the queue looking for the first empty slot (with a value of None). We could implement any seat picking strategy we fancy, this is just the easiest.

Once we find an empty seat, we create a new 'Member' object for the item, with position set to the current length of the queue, then increment the queue length. Also, if the queue has no empty slots, we raise an exception.

def pop(self):
    if self._length == 0:
        raise Exception("The queue is empty")
    for i, m in enumerate(self._queue):
        if m is not None:
            if m.is_next():
                value = m.value
                self._queue[i] = None
                self._length -= 1
            else:
                m.move_up()
    return value

Here we iterate over the queue looking for the member who is 'next' (has position 0). While we're looking for the next person, we also de-increment the positions of the other members.

Of course, this isn't how things work in practice. The barber doesn't go to each person and say "are you next?", "how about you?". They simply say "who's next?", and the person who believes they are next steps forward. Though arguably, that's just equivalent to asking every member concurrently. But let's not complicate things.

>>> b = BarberQueue(3)
>>> for i in xrange(3):
 b.push(i)
 
>>> print b
0 (0), 1 (1), 2 (2)
>>> b.push(4)

Traceback (most recent call last):
  File "<pyshell>", line 1, in <module>
    b.push(4)
  File "<pyshell>", line 36, in push
    raise Exception("Queue is full! Please come back later")
Exception: Queue is full! Please come back later
>>> b.pop()
0
>>> print b
_, 1 (0), 2 (1)
>>> b.push(4)
>>> print b
4 (2), 1 (0), 2 (1)
>>> for _ in xrange(4):
 b.pop()
 
1
2
4

Traceback (most recent call last):
  File "<pyshell>", line 2, in <module>
    b.pop()
  File "<pyshell>", line 46, in pop
    raise Exception("Empty queue!")
Exception: Empty queue!
>>> print b
_, _, _

So there we have it. Of course, this type of queue isn't really useful from a programming perspective.

All of insertion, deletion, and lookup are worst-case \(O(N)\), where N is the queue's capacity (not the number of people in the queue). Which is pretty much worse than all other types of queue.


Why do items keep disappearing from my queue?

Okay, let's move away from computer-sciencey queues. There are certain behaviours in real-world queues that don't apply or wouldn't make sense to programmatic queues.

For one, as I alluded to earlier, the capacity of the queue is not enforced - there's room for overflow, even if it means people have to stand.

But on the other hand, when a place does get that full, people are less likely to stick around.

In particular, we have two situations:


1) There's a non-zero probability that a person will not stick around if the queue is full or close to full. This probability will tend to be related to the length of the queue when that person arrives

\[p(not join) \sim f(capacity, length)\]

For example,

\[p(not join) = A\left(\frac{length}{capacity}\right) - C\]

where A and C are some constants relating to how likely the person is to stick around if the queue is 'full', and at what point they consider the place to be 'too full'.


2) There's a non-zero probability that a person already in the queue will leave before they're served.  This probability will typically depend on how long the person has been waiting, and how many people are still ahead of them

\[p(leave) \sim g(wait, position)\]

It's interesting because as time passes, wait increases, but position decreases. So how the probability evolves depends on how those factors balance against one another.

In particular, the probability evolution will likely depend on how each particular person responds to the sunk-cost fallacy - i.e. are they the sort to think "well, I've waited this long, I might as well see it through to the end", or do they think "this is taking too long, I've got better things to do with my time"?

For the sake of arguing, lets go with an exponential function for the general form.

For a sunk-cost person we might have

\[p(leave) = B \cdot \exp\left(-d\cdot \frac{wait}{position}\right)\]

This is a function where p goes to zero as position goes to zero or wait goes to infinity (B and d are some arbitrary constants).

Whereas for a non-sunk-cost person we might have

\[p(leave) = B \cdot \exp\left(-\frac{d}{wait \cdot position}\right)\]

This is a function where p goes to zero as position goes to zero, but goes to one as wait goes to infinity.

This gives us an interesting graph

Because 'position' is discrete you get this nice step function, with intervals of the probability steadily rising, then suddenly dropping. We can also see that there's a point at which probability of leaving is maximum, around the time you're in the middle of the queue. Which seems plausible.


We also have situations where a person will leave and come back later. But since, when they come back, they have to join the back of the queue, they're mathematically indistinguishable from a someone arriving for the first time.


One other complicating situation is people in groups. For example, if there's a parent and child ahead of you in the queue, the child is getting their hair cut by one member of staff, the parent is waiting; another member of staff asks 'who's next?' - is it you or the parent?

Situations like these add uncertainty into a member's queue position, and by extension their knowledge of whether they're next.

In that situation, we might wait to see if anyone else steps up, and if not we can assume it's our turn.

So we have \(p(next)\), which is a Bayesian probability that updates over time to reflect whether anyone else has stepped up yet. The longer we wait with no-one stepping up, the closer our probability gets to one.
Of course, if you wait too long, someone behind you might assume you're not in the queue after all and try to go ahead of you. But that's a topic for another blog.


Nothing's so simple that it can't be made complex

I've written about queuing before, in the context of a mathematical model of a cafe.

The long and short of it is this - people arrive at random (following a Poisson distribution) and join the queue with some probability (see above). Each iteration, some people are served, some join the queue, some get tired of waiting and leave, etc.

I'm going to iterate in 5 min time-step and say that a haircut takes 10-25 minutes (i.e. 2-5 steps). The exact duration is randomly generated for each customer.

I'm going to say that on average one person shows up every 10 minutes (0.5 per step). Here's an example of how that might look over 12 steps (one hour), using the Poisson distribution: [2, 0, 2, 0, 0, 0, 1, 0, 0, 1, 0, 0]

I set up the simulation so that you specify some number of steps for the barbers to be considered 'open'. After that, no more people are added to the queue, but the simulation keeps running until the queue is empty.

To begin with, I made it so that everyone who arrived stayed.

With 2 workers, capacity 10, and an arrival rate of 0.5, the queue length typically stayed below 3. The highest I saw it go was 7, which is still comfortably within capacity.
Above is an example of how the queue size varied over time in a particular simulation.

Increasing the arrival rate to 0.7, the average maximum queue length goes up into the low teens. And when the rate goes up to 1, the maximum queue length goes all the way up into the 30s.

Homework question - how does maximum queue length vary as a function of number of workers and arrival rate?

As I mentioned, those simulations assumed that everyone stuck around. Once you turn on probabilistic leaving, things get a bit more interesting.

I tried both versions of the leaving probability. The result was largely the same, except that sunk-cost people tend to leave sooner - average wait before leaving 2.6 for sunk vs 7.4 for non-sunk. This is what we'd expect - people adhering to sunk cost will tend to leave before they get too invested.

In the above example, orange is a time step when someone left the queue, and red is when a newcomer decided not to join the queue. I tuned the probability constants so that people don't start leaving until we're close to or at capacity, as we'd expect in real life.


You and I have different ideas of what constitutes 'interesting'

Going back to the original description of the barber's queue, here's an example of a full queue (bracketed numbers are queue positions)

542b5af6 (3), 33e323cf (5), 69e60241 (6), b3f12010 (0), fc89732e (7), 991f8709 (1), a0cb93cc (2), 17186c75 (4), 57269a3e (8), 8f1b61ca (9)

Notice how, even with the basic seat picking strategy (take the first available), the members aren't in a predictable ordered.


When we look at the waiting times, we can see some interesting things. For example
...
1c7081d1 waited 7.0
34 1
35 3
50be68cf waited 9.0
36 3
37 4
26ca11b7 waited 3.0
38 3
39 3
a571a7da waited 5.0

...

Here we have a person who had to wait 9 steps (45mins) to be served, followed by someone who only had to wait 3 steps (15mins). Which just goes to show, how long you wait in a queue is very much a matter of timing and luck.


It's also interesting that you can run the simulation multiple times with the exact same settings, and one time the queue will never go higher than 4, while in the the next it'll go as high as 13. This is complexity at work - various small random factors in the model interacting to produce wildly different outcomes.


So yeah. If you're interested, you can see the full code here. I may have gotten carried away with the object-orienting.


Oatzy.


[Post-Script

My boss recently pointed out that it'd been over a year since my last blog post. That was another perk of being unemployed - more time to come up with dumb blog posts. Anyway, here's a quick update on some stuff.


Pirate Game

The last blog post was about the making of an Android game - The Pirate Game.

The game is now finished-ish and has been released in 'beta' on the Play Store.

In the previous post, I mentioned that the game would eventually get a less utilitarian design. I ended up making that design myself (because I'm a control freak). I'm pretty pleased with how it turned out.
Also, following a... less than positive review, I added some new game play modes.

I never did figure out multiplayer, though. If I ever get the time or inclination to go back to the game, that'll be on the todo list. But for the time being, I don't anticipate any updates to the game. Certainly not any time soon.


New Job

So yeah. I finally got a job. I'm now a Software Developer at a company called Pixit Media.

The company sells large scale 'storage solutions' to companies primarily in the VFX industry, as well as universities and other such people that do high performance computing.

What I personally work on is primarily a Python API for the IBM Spectrum Scale (GPFS) filesystem. You can see the API docs online. I wrote a decent amount of the documentation (and the code that's being documented).

In particular, the 'Getting Started With List Processing' guide. Admittedly the topic is a bit niche - I doubt many readers of this blog even know of GPFS, let along have a cluster with it installed. But you might still find it interesting; you can learn some stuff about MapReduce - a technique for taking advantage of parallelism when processing large data-sets.

There's also the 'example scripts' repository - scripts written to use the API, some of while I wrote. But, again, they're a bit niche.

]

Sunday, June 28, 2015

The Pirate Game

A few months ago, my friend was telling me about this mobile game he wanted to make. He, and some of our other friends, are teachers, and this is a game they play with their students. The students apparently love it. And if there were an app version, they'd be willing to pay 59p for it. Or so they say.

Now, as he was explaining the game to me, I thought maybe he was building towards asking for my help. I felt almost betrayed that he didn't. Several years ago, I'd built a website for this friend that he'd had nothing but praise and gratitude for.

A month or so later, I got a text message - "How are you at programming?" For whatever reason, the guy they had originally 'hired' wasn't doing it anymore.

"I'm capable", I replied. I'd done a course in Java at university. Admittedly, that was 'Java for Mathematicians'. And it was also almost 8 years ago. But how hard could it be to pick up again? Just like coding a bicycle. Or something like that...


The Game

As the title of the blog suggests, its called 'The Pirate Game'. In the classroom it's played on paper.

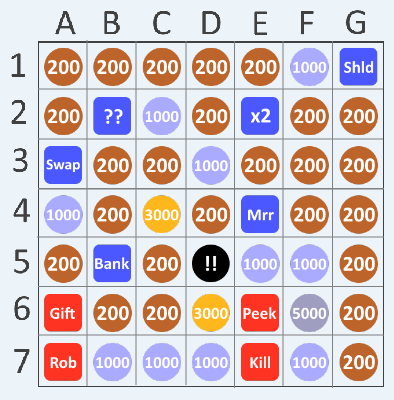
Basically, you have a 7x7 grid filled with items - mostly coins, but also some items that let you do other things. There are attacks that let you, for example, rob or kill other players. There's a shield and a mirror that let you defend against attacks. There's a bank item that let's you save whatever points you have from being stolen, etc. There's a bomb that blows you up (sets your points to zero). And so on.

This is the prototyping design. The final product will look less utilitarian.

At the start of the game, the players arrange the items in their grids to their liking. The teacher (game) then calls out random squares, and the players get whatever is in that square on their own grid. In the classroom, if a player gets an attack item, they have to raise their hand and tell the teacher who they want to use it on. The winner is whoever has the most points when all the squares have been called.


Making Games 1: The Right Tools

In a previous blog, I asserted that making mobile games was difficult. In fact, it turns out to not be so bad with the right framework. In this case I used the popular LibGdx. What's particularly nice about it is that there are a lot of how-to guides, and there's plenty of help for when things go wrong.

As they say, programming is 1% inspiration, 99% Googling.

For anyone interested in making their own Android game, I found these guides particularly helpful,

LibGdx Zombie Bird Tutorial
LibGdx Game Development Essentials
Set up Google Services with LibGdx


HAL9000

I got a first working version of the game done in the space of about a month - this was just the basic game mechanics, a bare-bones interface, and a single computer opponent that I could play against to check that the mechanics were doing what they were supposed to.

In those first few tests of the game, I found that the computer player kept beating me - at one point, 7 to 1. This seemed strange - neither I nor the computer could choose who we attacked, or which defences we used. So really, there wasn't anything either of us could do to influence the outcome of the game. The winner should have been totally random.

So loosing 7 times out of 8 seemed significant to me. As far as I could tell, the mechanics were working correctly. The only theory I could come up with was that maybe there was some advantage in the order in which we took our turns.

To try and figure out what was going on, I created a simulation. Basically, I re-wrote a very stripped down version of the player and game mechanics in Python. I then had two computer players play against each other in 10,000 matches. The results from this were - Player 1: 5005, Player 2: 4995.
In other words, the winner was just random chance. And turn order didn't matter.

If nothing else, this was a lesson in not drawing conclusions from such a small data set - it's not really statistically significant if there are only 8 data points (that's a standard error of ~3). After playing more games, the wins did end up averaging out.


Making Games 2: Coordinating Players

Development progressed. I got the full game mechanics working, and added more computer players (Clu and Ultron). I was now able to choose who I wanted to attack and what defences I wanted to use.

But the ultimate goal for the game is to let users play against their (human) friends. This meant I had to do a massive re-write to generalise the interaction mechanics.

Okay, lets look at an example of an interaction. Say I want to swap points with another player. First, my device needs to pop-up a player select dialog. Once I pick a target, the game needs to inform that player that I'm trying to swap points with them. If that player has a shield, their device needs to pop-up a dialog asking if they want to use it. The game then needs to inform me of my target's response - and if the target doesn't defend them self, we need to tell each other what our respective points are so that we can complete the swap.

That's a lot of back and forth to handle. Here are the rough diagrams I drew when I was trying to get the mechanics straight in my head.

I doubt this helps clarifies things for anyone else.

So the way the interaction works in the code is, the attacker sends their target a data object telling them who the attacker is, what attack they're trying to use, and what points they have (though the points aren't visible to the target). Once the target has chosen their defence, they complete their side of the attack processing - so in the swap example, if the target doesn't defend, they set their points to those of the attacker.

The target then sends the attacker's original data, along with the defence they chose (if any) and their (pre-attack) points to all the other players. If the recipient is the original attacker, they complete their side of the attack. Then, all players are shown a notification telling them what happened.
I figured I should give the computer players more piratical names.

All this coordination is done by a turn handler class. And what's nice is the computer players can also interact with each other, and with the local human player, via the turn handler.

All I need to do now is set up the stuff that actually sends the data between network players.


Game Theory

Through testing (looking for bugs and the like), I've played this game A LOT. And I've gotten a pretty good feel for how it works. It's actually quite fascinating when you really get into it. (Or maybe that's just Stockholm Syndrome talking).

Information is important to the game. Without it, players would be forced to make their moves at random. And when that happens, winning becomes mostly random chance. This is why players are shown notifications when other players interact - it allows them to strategise.

The most basic strategies are things like - rob people who have lots of points, don't try to rob people who have just been killed (they don't have any points to take), defend yourself when you have a lot of points (if you can). Really, this is just being sensible.

Then there are more subtle strategies. For example, sometimes it's better to lose a lot of points to the bomb or to being killed (removing those points from the game) rather than letting another player take them. Because, you don't need a lot of points to win, you just need more than everyone else.

Given the inherent randomness of the game, a lot of how you play will come down to how risk-averse you are. For example, a particularly risky strategy might be to let an opponent rob you (saving your defences), in the hopes that you can steal back your points, and more, later on.

When you play against humans (rather than AI), a whole bunch of social factors can come into play too. From what I hear, in the classroom, students tend to disproportionately target any members of staff that are playing. Though I can't imagine why.

One other interesting feature of the game is that it sometimes forces players to make disadvantageous moves. There's the bomb item that will take away your points when it inevitably comes up. And if you're in first place, the swap item forces you to give your points, and the lead, to another player.

So yeah, the game's not as simple as it might seem on the face of it.


Artificial Intelligence

In the first fully featured version of the game, the computer players made their decisions completely randomly. And that was fine - the game is perfectly playable with random opponents, it's not too easy, and the randoms can and will beat you on occasion. Sometimes by an embarrassing margin.

But random players also do things that don't make sense. So I wanted to create some computer players that used basic strategies to play more intelligently.

For interactions, these intelligent computer players (AI) use literal hit lists and avoid lists. As mentioned above, when two players interact, that information is sent to all other players. For humans, this information is displayed as a notification. For the AI, the information is processed to build/modify the hit and avoid lists.

For example, if Player 1 steals a lot of points from Player 2, then Player 1 is added to the hit list and Player 2 is added to the avoid list. If another player then kills Player 1, Player 1 is removed from the hit list and added to the avoid list. And so on.

If the AI then gets an attack square, they'll first check their hit list for a target. If the hit list is empty, they'll chose a random opponent who isn't on the avoid list. And so on.

There are also various basic heuristics for choosing which defences to use (and when), and for choosing a square when they get 'Choose Next'.

As they are, the AI are quite formidable, and at times frustratingly so. In general, I think it's better to have a mix of random and intelligent computer players. The AI offer a challenge, while the chaotic influence of the random players keeps things interesting.


Measuring Difficulty

In the game's current form, you can play against 2-7 computer players, and these players can be either random or 'intelligent' (as above).  That means 33 unique opponent set-ups. Which raises the question - how can we rate the difficulty of any given set-up. 

Obviously it's harder to win when there are more opponents. Specifically, the probability of a random player winning in a game of N random players is 1/N. Think of it like this - if all the players behave in the same way, they are indistinguishable. And if they're indistinguishable, they must all have the same probability of winning (turn order doesn't matter).

The same logic applies to intelligent computer players (AI) - since they all follow the same set of rules, they must also be indistinguishable from each other. Therefore, the odds of an AI winning in a game of N AI players must also be 1/N .

But what happens when there's a mix? How much harder are AI to beat than randoms?

To answer that, we can run some more simulations. This time, instead of re-writing code in Python, I created a modified version of the turn handler (see above) within the game project itself. Essentially I just removed all code that related to human players, and added a few bits to track statistics.

I set up the 33 different player configurations, ran 10,000 matches for each, and worked out the probability of winning for an AI player - for simplicity, we're assuming that a human player (playing strategically) is roughly equivalent to an AI.

From those simulations I made this lovely surface plot (using matplotlib).

Configurations with more than 7 opponents have been set to zero.

And what we find is AI are roughly twice as hard to beat as randoms - notice the surface is higher on the right hand side (when there are fewer AI).

In other words, your odds of winning in a match against two AI is roughly equal to your odds of winning in a match against four randoms. For simplicity, we're going to assume that the relationship is exactly two to one.

We can now calculate an approximation of the odds of winning as

\[ p(R, I) = \frac{2}{R + 2(I+1)} \]

And if we compare these probabilities to those from the simulations, we find that they are within standard error (order 0.01 for 10,000 trials).


To get a difficulty rating, we can just turn the probability on it's head, and normalise by the probability for the easiest set-up (2 random opponents). That is,

\[ D = \frac{p_0}{p} = \frac{R + 2(I+1)}{4} \]

This gives us a difficulty rating between 1 and 4, which lets us easily divide the difficulty into three levels - easy, medium, and hard. Though, if your odds of winning in the easiest possible game is only 50:50, can it really be considered 'easy'?

Another nice property of this difficulty rating system is that the difficulty ratios match the probability ratios - that is, your odds of winning a 2 are half your odds of winning a 1, and so on. Specifically, your odds of winning are roughly \( \frac{1}{2D} \)

Incidentally, if we assume our human player instead makes their moves completely at random, then their odds of winning are lower overall - \( p = \frac{1}{R+1+2I} \) - but the difficulty stratification works out the same.


Conclusion

Ordinarily, I'd include my code for this sort of thing. But in this case, doing so might undermine my (and my friends') income. And they very kindly told me that I'd get the majority of the profits. Whatever those may ultimately be.

So far we've made a whopping 7p (!) just from having adMob set up in the test builds.

But before we can make any (real) money, we have to actually finish the game. The single player version is mostly done, and should be released in the near future. The last big thing to do is the UI (which is someone else's problem job).

Then the hard part is going to be setting up multi-player with Google Play Services. In particular, because there aren't any good guides (that I can find) for setting up Google multi-player with LibGdx.

When it is done, I'll post links and such here for anyone that might be interested.

[edit] - If you want to try the current beta, you can get it here.

Also, given that making an Android game has turned out to be much easier than I expected, I may in fact make the previously discussed relativity game myself (once the Pirate Game is finished). In that case, I might also provide my code.


Oatzy.


[I'd love to make an AI that uses machine learning to counter human players' personal strategies.]

Monday, February 23, 2015

Designing a General Relativity Based Casual Game

Let's suppose, for the sake of arguing, that I'm unemployed. It'd pretty great if there were a way I could make a quick buck (or a quick quid, in my case). Obviously, the solution is to make a super addictive mobile game. Then I can just sit back and watch the cash come pouring in.

Okay, so that's a pretty terrible plan - making a mobile app of any kind is no trivial thing, and there's no guarantee of making any significant amount of money (or any money at all). Still, I thought about it, and wondered - if I were to make a game, what would I do. This is one of the ideas I came up with.


Game Concept

A common type of casual game is the physics-based game - that is, a game where objects obey a form of classical Newtonian mechanics: your Angry Birds, your Flappy Birds, your games that don't involve birds. So, for example, when you catapult an angry bird, it follows a parabolic path like a real bird would (drag not-withstanding).

And that's all fine, but I wondered if you could make a game based on non-classical physics - quantum mechanics, relativity, that sort of thing.

Now, I don't want to call this 'Interstellar: The Game' (not least because of copyright). That is, however, a good short hand for the idea behind the game.

The idea is this: you've been off exploring space, and now it's time to go home. So the main objective is to get back to Earth as quickly as possible, whilst dodging obstacles like planets, stars, black holes. But these massive objects have a gravitational pull, which can make maneuvering a little trickier, especially if you get too close to a black hole.

On the other hand, you can use massive objects to get a speed boost, by doing for example a powered flyby. But being close to massive objects for too long (black holes in particular) will cause time dilation, which might make you late home.


Game Construction

The way I imagine the game is as a 'side-scroller', where you move right to left (assuming the phone/tablet is held in landscape). I figure it would be a top-down view, moving in the x-direction with the spaceship - i.e. the sprite would be fixed in the x-direction, with freedom of movement up and down. All the obstacles would then move towards the sprite in the negative x-direction.

Here's what a (non-relativistic) binary orbit looks like from a frame of reference moving in the x-direction with the particle (blue).


In the code, this is done by calculating the particle velocity as normal, but instead of adding the velocity in the x-direction to the particle, you subtract it from all the obstacles.

For the sprite's up-down movement, you could either constrain the player to within the screen, or else if they drift off the edge of the screen, it would be a 'lost in space' game over.

Level construction can either be done by hand, or levels can be generated randomly / procedurally by adding massive objects of varying type/size/mass etc. at various points along the game map. I'd say go for random/procedural, since that makes creating levels easier, and would mean there are effectively unlimited levels. Though it might be worth storing generated levels for replayability.

For the representation of black holes, you could show an accretion disc (like they did in Interstellar), have a background star field that's gravitationally lensed, or show a dotted line for where the event horizon is. Alternatively, you could do nightmare mode - give no visual indication of a black hole, and let the player infer its presence from its gravitational pull.

I tend to think that controls should be kept simple, and should be appropriate to the medium - in other words, no on-screen d-pads on touchscreens (if you can help it). Instead, I'd say use four directional swipes for a speed boost in whichever direction. In terms of code, this would be done by adding some constant to the velocity in the direction of the swipe.

One thing to remember is that in space there is no drag - nothing to slow you down (gravity notwithstanding). Steering like this can be surprisingly tricky. If you accelerate left, you will keep moving leftwards until you accelerate right to counter balance.

On the other hand, no drag means the player could keep accelerating forward until they're going arbitrarily fast. To stop this, you could put a limit on how many times the player can accelerate - for example, say that there's a limited amount of fuel. This also means the player would have to use their fuel wisely - baring in mind that breaking counts as accelerating. This makes tricks like gravitational assists even more important.

Anyway, having an idea is all well and good, but really an idea isn't worth much if you can't prove that it's viable. So...


Game Mechanics

Preamble

I studied theoretical physics at university, and that included a module on General Relativity. But that module only covered the basics. As the lecturer pointed out, General relativity is a graduate level topic.

I read a bunch of articles for this blog, and have tried to get as scientifically accurate as possible - or at least I've tried to avoid making massive errors. But even so, there are numerous assumptions, approximations, and inaccuracies in this formulation. So just bear that in mind - I don't necessarily know what I'm talking about. Do feel free to offer corrections.

Prototyping - For coding the prototype/simulations I used Python with PyGame.

In PyGame, coordinates are defined with the origin (0,0) in the top right corner. This isn't a problem mathematically, it just means the graphical layout is 'upside-down'.

To make the videos in this post, I added the line
pygame.image.save(screen, 'output/frame%05d.png' % framenum)
to the code's main loop to save individual frames as a series of images (you'll need to iterate 'framenum'). I then used 'ImageJ' to convert those images to (avi) video.

Terminology - I'm going to refer to moving objects as 'particles', 'planets', or as a 'spaceship' in the context of the game. I'll refer to static, gravitating objects as 'obstacles', '(massive) bodies', or 'stars'. In images and videos, planets are blue, and stars are yellow.

Units - I chose to use 'pixels' as the unit of length, and 'frames' as the unit of time. In this case, velocity is measured in 'pixels per frame' (px/fr).

This is useful, because it means the velocity of our particle is updated as \(v(t) = v(t-1)+a(t)\) and the position is updated as \(x(t) = x(t-1)+v(t)\). For my simulation, I used a frame rate of 50fps.

Physical Constants - We could use geometrised units, where the Gravitational Constant (G) and the Speed of Light (c) are both set equal to one. In that case we wouldn't need to include them in the maths/code. However, my inner-mathematician likes generality, so I'm going to keep them around.

The constant 'G' only ever appears alongside obstacle masses (as GM), so we can set it to one and say that it's value is absorbed into the (otherwise arbitrary) mass values. It's worth keeping G around though, so we can easily tweak the strength of gravity, if need be.

The speed of light controls the strength of relativistic effects - larger c, weaker relativity. In my code I set the speed of light to c = 12 px/fr. This seems to make things behave in a way that looks 'right'.

Object Properties - We could try to go for a certain level of realism - try, for example, to work out a conversion between real world distances and pixels, try to get everything to scale. But that's too much faffing. Besides, if everything were to scale, a 1px Earth would orbit at a distance of 23000px around a 100px sun.

For obstacle masses, I set M = 500 (arbitrary units). The particle mass isn't really important since it can be cancelled out in all the equations. From a theoretical perspective, all that matters is that it's much smaller than the obstacle masses. I set both the obstacles and particle radii to 12.5 pixels (25x25px sprites). Object radii aren't important outside of collision handling.


Newtonian Gravity

For particle acceleration, we start with Classical Newtonian gravity.

\[ a = \frac{G M}{r^{2}} \]

where G is the gravitational constant, M is the mass of the gravitating body (the obstacle) and r is the distance between the centres of our particle and the obstacle. We're assuming that the particle is moving in a 2D plane, so we have \(r = \sqrt{dx^{2} + dy^{2}}\), where \(dx = x_p - x_{ob}\) and \(dy = y_p - y_{ob}\) are the x and y distances between the particle and obstacle.
This gives us the magnitude of the acceleration, pointing from the centre of the particle to the centre of the obstacle. For our purposes, we need to resolve this acceleration into x and y components.

The components are given by

\[ \ddot{x} = -\frac{G M}{r^{2}} \cos(\theta) \equiv -\frac{G M}{r^{3}} dx\\ \\
\ddot{y} = -\frac{G M}{r^2} \sin(\theta) \equiv -\frac{G M}{r^{3}} dy\]

Where \(\theta = \arctan\left(\frac{dy}{dx}\right) \) is the angle between the x-axis and the position/acceleration vector. The double dots mean 'second derivative with respect to time', i.e. acceleration.

If there are multiple gravitating objects, we have to calculate the contributions from each, and add them all together to get the total acceleration.

\[ \ddot{x} = -\sum_i \frac{G M_{i}}{r_{i}^{3}} dx_{i} \\ \\
\ddot{y} = -\sum_i \frac{G M_{i}}{r_{i}^{3}} dy_{i} \]

As mentioned above, once we have the acceleration we add that to the velocity, then add the velocity to the position to work out where the particle moves to. Below is an example of a Newtonian orbit using the above.


General Relativity

Since we want the game to include General Relativistic effects like time dilation, we also have to take into account the other effects of relativity - in particular, how it modifies particle motion/acceleration.

For simplicity, we're going to assume our obstacles (planets, stars, black holes) are uncharged, and non-rotating. In that case, we use the Schwarzchild metric, which describes the gravitational field in the vicinity of an (uncharged, non-rotating) massive object.

\[ c^2 d\tau^2 = \left(1 - \frac{r_s}{r}\right) c^2 dt^2 - \frac{dr^2}{\left(1- \frac{r_s}{r}\right)} - r^2 d\theta^2 \]

We're assuming the particle is moving in the 2D plane around the equator of the massive object. \(r_s\) is the object's Schwarzchild radius (also known as the 'event horizon' in the context of black holes), defined as

\[ r_s = \frac{2GM}{c^2} \]

Without going into too much detail, we can derive from the Schwarzchild metric the particle's acceleration in Cartesian-like coordinates as

\[ \ddot{x} = - \frac{G M}{r^3} dx - \frac{3 G M L^2}{c^2 r^5} dx \\ \\
\ddot{y} = - \frac{G M}{r^3} dy - \frac{3 G M L^2}{c^2 r^5} dy \]

Where the first term is the classical Newtonian gravitation, as seen above.

The second term is purely relativistic, and will usually only have a significant effect when a particle is sufficiently close to a massive body's Schwarzchild radius.

The main effect of this term is to increase gravitational acceleration in the vicinity of the massive object, and to cause close orbits to precess, as can be seen below


Notice that the point at which the particle is closest to the 'star' (the perihelion) moves over time. This doesn't happen in the classical limit of Newtonian gravity. In fact, explaining the anomalous precession of Mercury was one of the first pieces of evidence supporting the theory of General relativity.

In the acceleration equation, L is the angular momentum (per unit mass) of our particle, and c is the speed of light. Angular momentum (per unit mass) is calculated as

\[ L = \left|r\right| \left|v\right| \sin(\phi) \equiv (dx\ v_y - dy\ v_x) \]

where \(\phi\) is the angle between the radial vector (r) and the velocity vector (v)

The angle can be calculated as

\[ \phi = \alpha - \theta = \arctan\left(\frac{v_y}{v_x}\right) - \arctan\left(\frac{dy}{dx}\right) \]

where \(\alpha\) is the angle between the velocity vector and the x-axis, and \(\theta\) is the angle between the position vector and the x-axis.

In the two body case, angular momentum is a constant of motion, so only needs to be calculated once - say, once the particle's initial position and velocity has been set.

Caveat - Strictly speaking, the radial length 'r' in the Schwarzchild metric is not the same as the Euclidian distance \(\sqrt{dx^2 + dy^2}\). At least, not when relativistic effects are significant. Rather, r is defined as the circumference of a sphere surrounding the massive body, divided by \(2\pi\). Defining r this way means the length of an interval dr isn't affected by the curving of spacetime near the massive body.

By comparison, an observer falling towards a black hole would see lengths stretching longer and longer the closer they got to the black hole event horizon - an observer at a distance r would measure the interval dr to have a length of \( \left( 1 - \frac{r_s}{r} \right)^{-\frac{1}{2}} dr \).

All this to say, the particle distances displayed in the game (and the simulation videos) are distances in Schwarzchild coordinates, projected onto a Euclidean plane, not distances as viewed by an observer such as our particle/spaceship.


Relativity for Multiple Bodies

This is where things get dicey. In the General relativistic limit, combining the fields of multiple massive objects is not so straightforward.

The lazy way of doing this is to just vector sum the relativistic accelerations, like we did for the Newtonian case. This is problematic, though, because it assumes the particle's angular momentum around each massive body is constant. This is not true.

Instead, we can make a simplification - we can sum the Newtonian terms as before, but we'll only consider the relativistic term when we're sufficiently close to any given body. This cut-off is going to be fairly arbitrary. Ideally, we want the 'radius of influence' to be as big as possible, but small enough that the particle can never be within the relativistic limits of more than one body at a time. The main problem here is that the way the game is set up means all the massive bodies are unrealistically close together, so it's hard to make the radius of influence big enough to be ideal. In my code, I chose the cut-off to be \(10 r_s \simeq 70px\).

Now, the angular momentum around this close body is still not constant (although, arguably, it may be sufficient to assume it is). The forces from other local bodies can cause torque, which will change the particle's angular momentum.
Torque is calculated as

\[ \Gamma = \left|r\right| \left|F\right| \sin(\gamma)\ \equiv r_x\ F_y - r_y\ F_x\]

where \(\gamma = \theta_1 - \theta_0 = \arctan(\frac{dy_1}{dx_1}) - \arctan(\frac{dy_0}{dx_0}) \) is the angle between the position vector (r) and the force vector (F), and \(\theta_0\) and \(\theta_1\) are the angles between r and the x-axis, and F and the x-axis, respectively.

For the force from a gravitating body, the torque can be written out as

\[\Gamma = \frac{G M_1 }{r_1^3} \left(dy_0\ dx_1 - dx_0\ dy_1\right) \]

We only need to take into account Newtonain gravitation in calculating torque, since we're already assuming the particle is outside the relativistic limit of these other bodies.

So once the particle enters a massive body's radius of influence, we calculate it's initial angular momentum, as above. Then, in each time step (for as long as the particle is in the radius of influence), we calculate the total torque from all local bodies, and add that torque to the particle's angular momentum (before calculating the new acceleration).

This is a big simplification. But it's good enough, and correct in the limiting case of a single/well isolated body. Especially if the radius of influence can be made sufficiently big.

While we're on torque - if our spaceship accelerates (fires its thrusters) while it is close to a massive body, we will need to take into account any torque from that as well

\[ \Gamma = dx_0\ a_y - dy_0\ a_x \]

Where \(a_x\) and \(a_y\) are the x and y accelerations caused by the thrusters. This is ignoring the details of how a spaceship actually maneuvers. If you're interested, you'll have to look into that for yourself.

So putting it all together we have

\[ \ddot{x} = -\sum_i \frac{G M_i}{r_i^3} dx_i \ - \frac{3 G M_0 L_0^{2}}{c^2 r_0^{5}} dx_0\\ \\
\ddot{y} = -\sum_i \frac{G M_i}{r_i^3} dy_i \ - \frac{3 G M_0 L_0^{2}}{c^2 r_0^{5}} dy_0 \]

where \(M_0\) is the body whose radius of influence the particle is within (if any), and

\[L_0 = L_{0}(t-1) +\sum_{i\ne 0} \frac{G M_i}{r_i^3}(dx_i\ dy_0 - dx_0\ dy_i) + (dx_0\ a_y - dy_0\ a_x)\]


Time Dilation

For a single massive object, the time dilation can be derived from the Schwarzchild metric (see above). Dividing through by \(c^2 d\tau \) and rearranging we get

\[  \left(1- \frac{r_s}{r}\right)^2 \left(\frac{dt}{d\tau}\right)^2 = \left(1- \frac{r_s}{r}\right)\left(1 + \frac{r^2 \dot{\theta}^2}{c^2}\right) + \frac{\dot{r}^2}{c^2} \]

where the dots mean 'derivative with respect to \(\tau\)'. And since \( \dot{r}^2 + r^2 \dot{\theta}^2 \equiv v_x^2 + v_y^2 = v^2 \), we can re-write and rearrange further to get

\[ dt = \frac{d\tau}{\left(1- \frac{r_s}{r}\right)}\sqrt{1- \frac{r_s}{r}\left(1 + \frac{r^2 \dot{\theta}^2}{c^2}\right) + \frac{v^2}{c^2}} \]

where dt is the 'coordinate time' - time as measured by an observer at rest, far away from any gravitational fields. For the sake of the game we can say that this represents time as measured on Earth. In reality, the Earths gravitational field does cause it's own time dilation effect. \(d\tau\) is the 'proper time' - time as measured by a clock on our spaceship.

Notice, in the limit of a stationary particle, that is \(\dot{r}=r\dot{\theta}=0\), we get the purely gravitational time dilation

\[ dt = \frac{d\tau}{\sqrt{1 - \frac{r_s}{r}}} \]

Similarly, in the limit of \( r \gt\gt r_s\) (i.e. when our particle is far from any gravitating bodies), the time dilation equation reduces to the Special Relativistic case

\[ dt = d\tau \sqrt{1 + \frac{v^2}{c^2}} \]

Note - in this, the velocity v is the 'proper velocity' - velocity with respect to proper time. This is different from coordinate velocity - velocity with respect to coordinate time.

While a particle can't have a coordinate velocity greater than the speed of light 'c', because of time dilation it can have a proper velocity greater than 'c'. This doesn't, however, mean that a particle can travel faster than light, since light has a proper velocity of infinity. Coordinate velocity and proper velocity are related by

\[ v_c = v \left(\frac{d\tau}{dt}\right) \equiv \frac{v}{ \sqrt{1+\frac{v^2}{c^2}}}\]

where the equivalence is true in the Special relativistic limit. Notice that when proper velocity equals the speed of light (c), the coordinate velocity equals \(\frac{c}{\sqrt{2}}\) - less than the speed of light.


Time Dilation for Multiple Bodies

Here, we once again have the problem of combining the effects of multiple gravitating masses. Some would argue, at this point, that trying to be scientifically accurate is more trouble than it's worth. Still, I'm going to at least try.

To start, we can replace the Schwarzchild radius terms with the local (Newtonian) gravitational potentials as

\[ \frac{r_s}{r} = \frac{2GM}{c^2 r} \rightarrow  \sum_i \frac{2 G M_i}{c^2 r_i} =  \sum_i \frac{2U_i}{c^2} = \frac{2U}{c^2}\]

Where \(U_i\) are the individual gravitational potentials of the various local gravitating bodies.

For the term in \(r^2 \dot{\theta}^2\), we note that \(r^2 \dot{\theta}^2\ = \frac{L^2}{r^2} \), where L is angular momentum (per unit mass). So we can use the same trick we did for combining accelerations - that is, only take this term into account when the particle is within a body's radius of influence.

So putting it all together, we have

\[ dt = \frac{d\tau}{\left(1 - \frac{2U}{c^2}\right)}\sqrt{1 - \frac{2U}{c^2} - \frac{2U_0}{c^2}\frac{L_0^2}{r_0^2 c^2} + \frac{v^2}{c^2}} \]

With \(L_0\) defined as above. Alternatively, we could just omit the angular momentum term since it's of order \(c^{-4}\). In my simulation, it amounted to a ~0.17% decrease in the dilation ratio.

The typical dilation ratio in my simulation was \(\frac{dt}{d\tau} \approx 1.07\), which admittedly isn't significant.

In the movie Interstellar, a lot of the time dilation came from the fact that their black hole (Gargantua) was spinning very fast. If you want to do that, you'll have to work it out for yourself - for that you would use the Kerr metric. With rotating black holes, you'd also need to take into account other effects like frame dragging.

Of course, we've chosen arbitrary masses, an arbitrary speed of light, distances not to any sort of realistic scale. We can always tweak the specific time dilation to our liking. In particular, if the realistic dilation isn't dramatic enough, we could artificially inflate it. So long as we keep key behaviours, like dilation going to infinity when the particle reaches a black hole event horizon, etc.


Collision Handling

Collision handling is important for figuring out when the game is over - for figuring out if the player crashed into a planet, or fell into a black hole. Now, PyGame has in-build collision handling. But where's the fun in that.

The easiest way to check if two circular objects have collided is to check if the distance between their centres is less than the sum of their radii

In other words, we have the condition - a collision occurred if \( dx^2 + dy^2 \le (r_p + r_{ob})^2 \).

Easy. There is a special case though - because the particle moves in discrete steps from frame to frame, if the particle is moving fast enough, it could move from one side of an obstacle to the other without ever overlapping.

The basic collision handling would miss this. So this is a little trickier to catch. In the above diagram, I've traced the path going from the particle's position in the previous step to its current position.

We can say that the particle collided with the obstacle if there's a point on that path that's closer to the centre of the obstacle than \( R = r_p + r_{ob} \). In other words, if the particle had moved continuously along the path from \(x_0\) to \(x_1\), would there have been any point(s) where the particle and the obstacle overlapped.

To figure this out, first we find the equation for the line passing through the particles' two positions as

\[ y = m x + c = \left(\frac{v_y}{v_x}\right) x + \left(y_0 - \frac{v_y}{v_x} x_0 \right) \]

(in this case, m and c are gradient and constant, respectively, not mass and speed of light).

Second, we're going to define a function for the distance between a point on the particle's path and the obstacle's centre

\[ f(x) = (x_{ob} - x)^2 + (y_{ob} - y)^2 = (x_{ob} - x)^2 + (y_{ob} - m x - c)^2 \]

Now we're going to look for the point along the path of closest approach to the obstacle. To do that we look for x such that the separation f(x) is minimised. In other words \( \frac{d}{dx} f(x) = 0\)

If you work through the maths, you get

\[ x_{min} = \frac{x_{ob} + m y_{ob} - m c}{1 + m^2} \]

Which gives us the condition - a collision occurred if \(f(x_{min}) \le R^2\) and \(x_0 \le x_{min} \le x_1\) (assuming \(x_0 \le x_1\)).
Both these collision handlers can also be used to check if the particle crosses a black hole's event horizon - just replace \(r_{ob}\) with \(r_s\), the Schwarzchild radius.

Of course, in the game, the spaceship sprite wouldn't be circular. But, you know. You could create an 'imaginary' circle around the sprite, or give the sprite a radius of zero (so it collides when its centre overlaps the obstacle). Or you could just use a third party library. Either way.


Bonus: Elastic Recoil

For my own amusement, I had the particle elastically recoil off of the obstacles, as well as the sides of the screen, so that I could just watch it drifting and bouncing about endlessly. It's weirdly hypnotic.

For screen boundaries, you have, for example
In this case, we flip the particle velocity in the x-direction as \( v_{x}' = -v_{x} \), and move the particle's x position to \( x_{p}' = W - (x_{p} - W) = 2 W - x_p \), where W is the pixel width of the game window. You do the same sort of thing for the other 3 boundaries.

For recoil off obstacles, things are not so straight forward. The procedure works like this: First, check for a collision. Then, find the point along the particle's path where it first makes contact with the obstacle - that is where \(f(x) = R^2\).
Finding this point is just a matter of solving a quadratic equation to get

\[ \begin{align*}
x' &= \frac{x_{ob} + m y_{ob}-mc}{1 + m^2} \pm \frac{\sqrt{(x_{ob} + m y_{ob}-mc)^2  - (1+m^2)(x^2_{ob} + y^2_{ob}+c^2 - 2 c y_{ob} - R^2)}}{1 + m^2} \\ \\ &\equiv a \pm b
\end{align*} \]

If \(v_x \gt 0\) then x' = a - b, if \(v_x \lt 0\) then x' = a + b

So move the particle back to the point of first contact. Then we want to flip the particle velocity so that the angle of incidence \(\phi\) between the velocity vector (v) and the position vector (r) equals the angle of reflection
The new velocity is given by

\[v'_x = -\left|v\right| \cos(\beta)  \\ \\ v'_y = -\left|v\right| \sin(\beta)\]

with \(|v| = \sqrt{v_{x}^{2} + v_{y}^{2}} \), and

\[ \beta = \alpha - 2 \phi = 2\arctan\left(\frac{-dy}{-dx}\right) - \arctan\left(\frac{v_y}{v_x}\right) \]

where \( \alpha \) is the angle between the x-axis and the old velocity vector (v), and \(\beta\) if the angle between the x-axis and the new velocity vector (v').

Note - in the code I used 'arctan2(y,x)' from the Numpy library, for which the signs of 'x' and 'y' are important. dy and dx are negative in the above because I have the position vector pointing from the particle to the obstacle (opposite to how it's defined).

Finally, we want to move the particle to where it should be from recoiling.

In other words, we want to move the particle to the point along it's new velocity vector, such that it's the same distance from the contact point as it would be if the particle hadn't collided. To do this, we can just resolve the distance \( r' = \sqrt{(x_1 - x')^2 + (y_1 - y')^2} \) in the direction of the new velocity vector, as

\[ x_1 ' = x' - r' \cos(\beta) \\ \\ y_1 ' = y' - r' \sin(\beta) \]

Admittedly, this doesn't work perfectly - sometimes it behaves a little screwy. Especially when the particle spirals in on an obstacle. Of course, none of this recoil stuff is necessary for the game, since you want collisions to end the game. Like I said, this was more for my own amusement.


Conclusion

If you were feeling really ambitious, you could do the game from the first-person perspective of someone on the spaceship - see for example 'Falling into a Black Hole', or the Interstellar papers.

There are almost certainly things wrong with this 'formulation' of General Relativity. But then, this is meant to be for a game, so it doesn't need to be 100% scientifically accurate. I did feel like I should make an effort, though. And I'm willing to call this good enough. If you're someone who knows what they're talking about, feel free to offer your thoughts/corrections.

Anyway, I've done my job as a theoretician - now it's up to someone else to actually make the game. If you do, please send me link to the completed game. And maybe give me a name-check? A little kickback would be nice too... ;)

You can have a look at my prototype/simulation code here.


Oatzy.


[Gravity, don't mean too much to me.]

Thursday, September 18, 2014

#IceBucketChallenge - A Viral Campaign

I know this blog is a little late to the game. In fact, I started writing it while it was still relevant... but then I got distracted. Such is life.


Background

You probably already know (or vaguely remember) what the Ice Bucket Challenge is. Basically if you're nominated you have to dump a bucket of ice water over your head, or else you have to donate money to some charity - most commonly ALSA, the Amyotrophic Lateral Sclerosis Association.

You then nominate 3 more people, who have 24 hours to do the same thing. In some variants, you also make a small donation even if you dump the ice water over your head, or else you make a bigger donation if you don't (some specify $100).

Anyway, what I was interested in is how the challenge spread - this was a 'viral' campaign in a very true sense. So why not try to model how the campaign spread as we would model the spread of a virus?


The Viral Model

I've written about this sort of thing several times before. The basic idea is this - the population is divided into three groups:

Susceptible (S) - The population that hasn't been exposed to a disease/virus, but is susceptible to infection
Infectious (I) - The people who have been exposed, and can infect other people
Recovered (R) - The people who have been infected, but have recovered. It's generally assumed that these people can't be re-infected. (But there are variations).

For the ice bucket challenge, we can look at a direct analogy as

S - Those who haven't been nominated
I - Those who have been nominated and are taking the challenge (so can nominate other people)
R - Those who have completed or those who declined the challenge (and can't nominate anyone else)

We can draw the model as a flowchart, showing how people move between the different groups,

Here, we've divided nominees into those who accept the challenge (S->I) and those who don't accept (S->R). So, now we can describe the model as a system of differential equations,


Where the factors (α, β, γ) describe what proportions of each group move to where.

The most interesting part is the 'S*I' terms in the first two equations - this basically says that the number of newly infected people is proportional to the number of susceptible people AND the number of infectious people.

This makes the system self-limiting, meaning that the number of infected people can't just grow to infinity - since that's not what we observe. Instead, what we see is an increase to some maximum, followed by a steady drop-off. For example,

We don't have hard data on how many people did the challenge over time, but we can get an idea of what happened by looking at the YouTube search numbers for the phrase 'ice bucket challenge' (above, via Google Trends).

I mean, it seems reasonable to assume some loose correlation between the number of people doing the challenge, the number of videos of people doing the challenge, and the number of searches for those videos. Searches peaked on August 21st, in case you were wondering.


A More Discrete Model

The downside to this 'S*I' term is that it makes the equations non-linear, meaning they can't be solved analytically - that is, you can't come up with an 'exact' equation for the number of people doing the challenge on a given day, for example.

But we can do a numerical simulation, instead.

In fact, this is a more reasonable way of looking at the system, since we're interested in a discrete time step of one day - i.e. the 24 hours nominees have to complete the challenge. For the simulation, we're also going to rounded the numbers of people in each group (after each time step) to whole numbers, since you can't (or shouldn't) divide a person into fractions.

Now, we need to define some parameters. First of all we need to define our start populations. We'll call the initial susceptible population S0 - this could be, for example, the Earth's population (which was around 7.16bn when I ran my simulations). We'll assume that one person is infected as a starting point  - the originator of the challenge (I0 = 1). And we'll assume that no-one else has done the challenge at the start, so R0 = 0.

For the constants (α,β,γ), the easiest one to define is γ - the 'recovery' rate. We assume that after the 24 hour challenge period nominees are no longer 'infectious', therefore γ = 1.

For α and β, we have the total rate of infection/nomination defined as (α+β). We're given that each challenge completer gets to nominate three new people, so we can define (α+β) such that in the first step (when there's only one infectious person) we have (α+β)*S0*I0 = (α+β)*S0 = 3. Therefore (α+β) = 3/S0.

Now, α and β are related to the proportions of nominees that accept and decline the challenge, respectively. So we can redefine the constants as α = a/S0 and β = b/S0, such that (a+b) = 3, or alternatively α = a/S0 and β = (3-a)/S0. So now we can look at 'a' as the average number of nominees who accept the challenge.

So to tie it all together, we have the system of (difference) equations,

And it's pretty straightforward to write some code that'll run through those equations.


So we've got our model, what now?

Having a model is all well and good, but why bother? Well, now we can start asking questions. For example, how fast does the campaign spread? How long will it take for the challenge to die out, and how many people will have taken part by that point? And what happens when we change the number of people who accept the challenge?

First of all, if we run the simulation (with a = 2.5) and plot I(n) - the number of people doing the challenge on any given day - we get something like this


[where I(n) has been normalised so that the maximum is 100, as Google Trends does].

This is about what we expected - a rise and a fall. Though it's worth noting the shape is a little different from the YouTube searches above; the simulation drops off quickly, while the search numbers have a longer tail. This could be because, even after the challenges are done, there's a latent interest in (re)watching the videos. Or it could just be that this model is not entirely accurate...


So what happens when we vary 'a'?

We can start by assuming everyone accepts the challenge (a = 3). In this case, eventually everyone in the world does the challenge - specifically within 21 days of the first challenge. But that isn't very realistic.

So let's say that on average 1.5 or 2 of those challenged accept. In these cases, the ice bucket phenomenon ends before everyone can be challenged. For a = 2, the challenge ends after 50 day, with ~13% of the population going unchallenged. On the other hand, for a = 1.5 the challenge takes significantly longer to end (over a year).

In fact it turns out that for any a < 1.6030165.. the challenge will take a significant amount of time to end - the number of 'infectious' people will eventually reach 1, and stay there until S <= S0/(2a) (remember we're rounding each group to the nearest whole number). For a <= 0.5 the challenge ends almost immediately.

Now, we know that for a = 3, the population S goes to zero (everyone is challenged), whereas for a = 2 the challenge stops before S can go to zero. So we have the question - what is the smallest value of 'a' for which S goes to zero? If you do a bit of interpolating, you can figure out that this critical value comes out at around 2.7405349.. At this value of 'a', the challenge ends after 23 days. In other words, if on average 2.74.. (~91%) of the people nominated accept the challenge, then after 23 days everyone in the world will have been challenged.

From what I've seen myself, it seems like nearer 1 in 3 people accept the challenge on average. So, as viral as the campaign was, it was never going to take over the world.

If you play around a bit, you'll find that the critical values of 'a' are dependent on the initial population (S0). But, as far as I can tell, it's not possible to derive these critical values analytically. (Answers in the comments if you can prove otherwise).


Why wait to be nominated..?

At this point, you're probably thinking this isn't a very realistic model. And you'd be right. So lets make it a bit more complicated.

In particular, lets add spontaneous participation - that is, people who aren't directly nominated, but who see all the other people doing the challenge, and decide they want to take part too.

We'll assume that this participation is proportional to those who have already done the challenge (I and R). So to start with, we need to separate the 'recovered' group into those who actually did the challenge (R), and those who declined (D).

The new model looks something like this,


With difference equations,

In the flowchart, we've introduced this new factor 'δ', the 'inspiration' rate. If we re-define it, like we did for the infection rate, as d/S0, then 'd' can be loosely interpreted as the average number of people inspired to take part by each person who's already done the challenge.

Now we can look at how this 'd' factor affects the things we looked at before - how long it takes for the challenge to end, etc.

Let's start by assuming that the average number of nominees accepting the challenge, 'a', is 1 (out of 3). What value of 'd' do we need for S to go to zero? Do a little interpolating again and you get d = 0.8668653 - that is, if each person who pours a bucket of water over their head inspires (on average) 0.867.. people to do the same, then everyone in the world will participate, within 26 days of the challenge starting. For a = 2, we need d = 0.4046021 for S goes to 0. And so on...

What's a plausible inspiration rate? For a normal person, probably zero, while for a celebrity... I don't know. But on average 'd' is probably very close to zero. I mean, we know for a fact that significantly less than the entire population of Earth has been nominated/taken part in the challenge.

If you plot I(n) for a = 1 and d = 0.1 you get something like this,


In this case, you have that same rise and fall - but this time, you have a longer tail, like we see in the YouTube searches. Is this proof that this iteration of the model is more accurate? Maybe. But as I pointed out before, the YouTube searches don't necessarily accurately represent the number of people taking the challenge over time.


Social Pressure

When a friend does a thing for charity, then publicly calls you out to take part, there's a certain amount of social pressure to comply. I mean, if a friend dumped water over their head (just because), then asked you to do the same thing, probably you'd look at them like they were a crazy person. Anyway, that kind of social pressure is implicitly included in the 'infection' rate - more social pressure, bigger 'a'.

Instead, the sort of social pressure I'm talking about here is the kind that goes: "I should accept the challenge because so many other people have already done it". Or alternatively, "it's okay for me to accept the challenge, since so many other people have already done it".

In other words, the more people accept and complete the challenge, the more likely a nominated person is to accept too. Mathematically, we can introduce this with a term in 'S*I*R'. Or alternatively, we can keep the term as 'a*S*I', but make the factor 'a' a function of R -> a(R).

Anyway, if you're interested, you can try investigating that yourself. Or try adapting the model in some other ways. But beyond a point you can end up complicating a model more than improving it.


A Network Theory Approach to Nominating

So I was eventually nominated for the challenge. But I'm a wimp, so I declined to dump ice water over my head, instead making a donation to the Motor Neuron Disease Association (the UK equivalent of ALSA).

For my nominations, I wanted to try and maximise spread. So I nominated the 3 of the people in my Twitter network who are the most active and well connected, and who I thought would be up for accepting the challenge. Plus, as a secondary effect, I figured they might nominate other people in my Twitter network - the network theory equivalent of wishing for more wishes.

In the end, one ignored the nomination, one acknowledged but didn't accept, and one accepted (in the form of a donation) but didn't nominate anyone else. So I guess that theory didn't quite pan out. But I did at least encourage more charitable giving.


So Yeah

If we had real world data we could maybe test the accuracy of these models. But even without, we can get a sense of how the challenge behaves - for example, we find that there's a critical 'challenge acceptance ratio' that determines whether the viral campaign will go 'pandemic'.

In theory, you could apply this sort of model to any viral campaign, or just anything that spreads 'virally'. The nice thing about the Ice Bucket Challenge in particular, though, is that it has well defined rules for how the challenge spreads from one person to the next.

So, yeah..


Oatzy.


[I need an editor, my pronouns are all over the place.]